{{ c.k }}
{{ c.v }}
{{ c.d }}
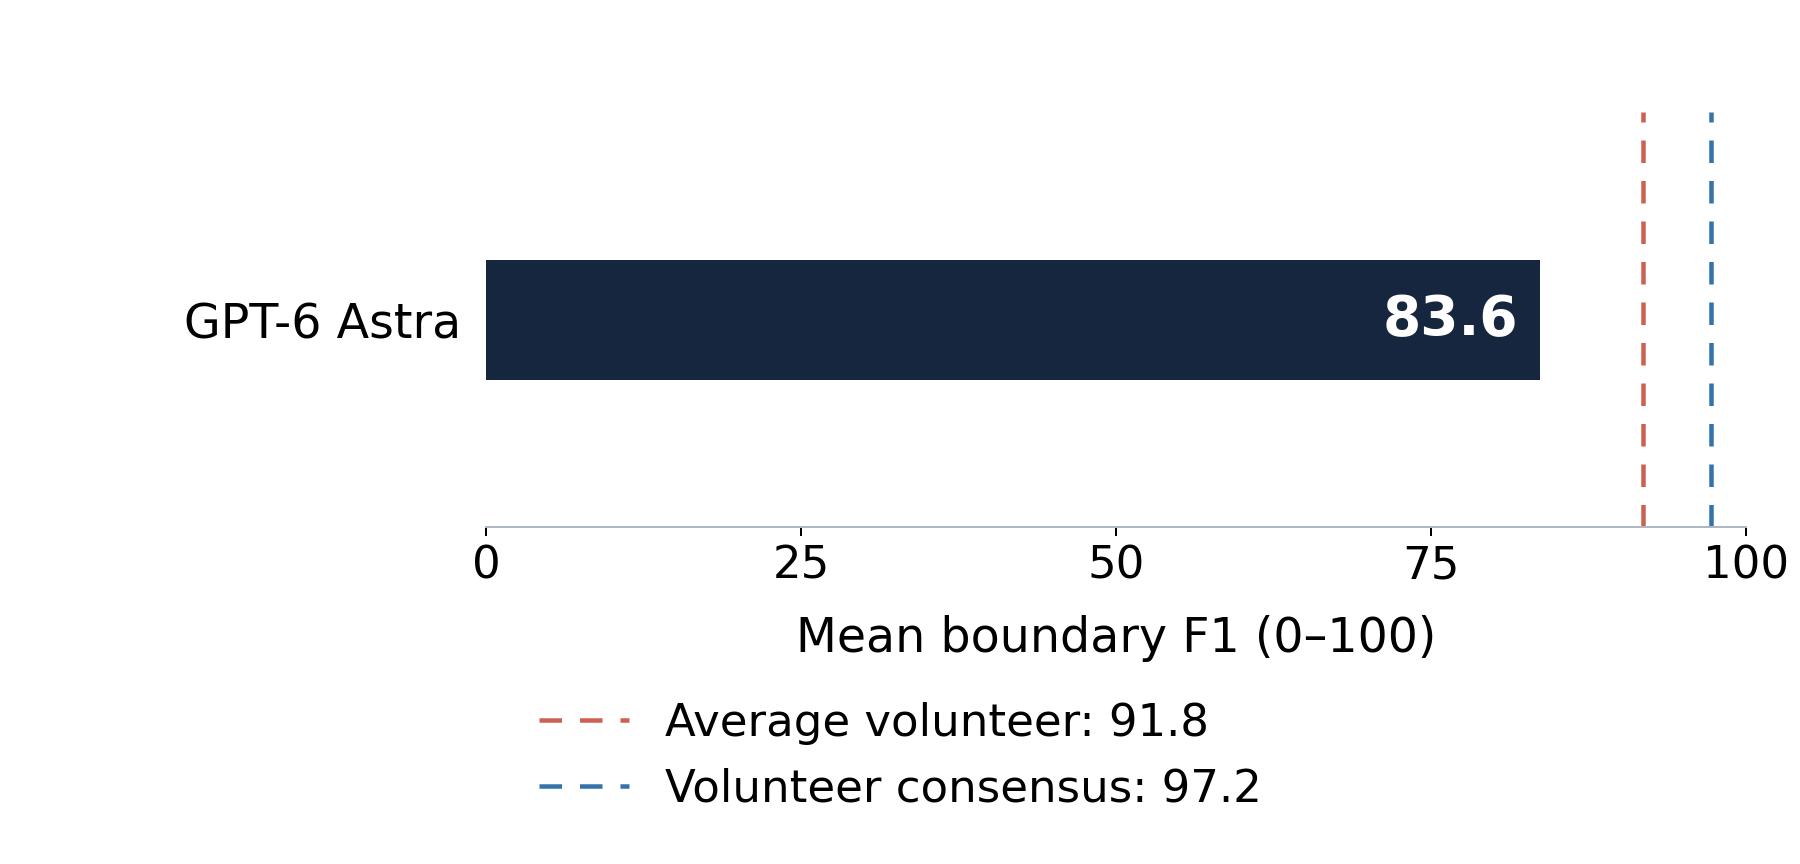
All 100 images are included, 25 from each of the four datasets. Scores use boundary F1 with a five-pixel tolerance on the 300 × 300 model inputs. The subject viewer shows the single GPT-6 Astra run from October 1, 2026, at low reasoning with the tutorial included and optional field guide off.
98 references are supplied expert consensus. The two replacements use volunteer consensus. On those two, consensus scores 100% by construction and individual volunteer responses contribute to their reference.
Models produce complete final outlines. Volunteers used the original machine-correction workflow. The volunteer baseline averages nonempty responses within each subject, then across subjects: 1,607 responses, excluding 17 empty drawings. Empty model predictions score zero. The volunteer consensus includes the two agreed contour removals.
The expert-only 98-subject means are 83.7 for Astra, 91.7 for individual volunteers, and 97.1 for volunteer consensus. The purple bouton outline is part of the supplied image. Overlay colours: green reference, cyan Astra, pink volunteer consensus. The five-pixel scoring tolerance is not shaded in the viewer.
Download bar chart · Download all 100 scores · All campaigns
Reference: {{ s.referenceLabel }}. {{ s.referenceNote }}
{{ s.raw }}